AI and the Sanskrit Revival in 2026: Language Models, Manuscript OCR, Translation Tools and What AI Still Gets Wrong
Sanskrit is having an AI moment: open translation models, a 391,548-sentence training dataset, a national manuscript mission built around handwritten text recognition, a B.Tech in AI at a Sanskrit university and two announced Sanskrit LLMs. Here is what exists, what is only announced, and why AI still finds Sanskrit hard.
Sanskrit is having an AI moment: open translation models, a 391,548-sentence training dataset, a national manuscript mission built around handwritten text recognition, a B.
Quick answer: In 2026 AI is genuinely helping Sanskrit, mostly in three areas: translation (open models such as IndicTrans2 and Dharmamitra, and a new 391,548-pair training dataset), text analysis (ByT5-Sanskrit for segmentation and tagging) and manuscripts (the Gyan Bharatam Mission's AI and handwritten text recognition work). Two Sanskrit LLMs were launched or announced this year. But Sanskrit remains hard for AI, not easy: benchmarks class it as low-resource, and translation of compounds and philosophical ideas still needs human checking.
Here is a surprising true fact: the most popular claim about Sanskrit and computers is almost exactly backwards. WhatsApp forwards say Sanskrit's perfect grammar makes it ideal for AI. The researchers actually building Sanskrit AI describe it as a "morphologically rich" language that is "notoriously challenging" for natural language processing (Source: Nehrdich, Hellwig & Keutzer, ByT5-Sanskrit, 2024). The real story of AI and Sanskrit is not about a language that machines find easy. It is about scholars, engineers and institutions doing difficult work to make a classical language accessible again.
The tools that exist: models and datasets
| Tool or dataset | Who / when | What it does |
|---|---|---|
| IndicTrans2 | AI4Bharat; paper May 2023, long-context variants January 2025 | Open-source translation across all 22 scheduled Indian languages, including Sanskrit |
| ByT5-Sanskrit | Nehrdich, Hellwig, Keutzer; September 2024 | One model for segmentation, lemmatisation, tagging, Vedic dependency parsing and OCR post-correction |
| Dharmamitra | UC Berkeley (BAIR); August 2024 | Neural grammatical analysis and Sanskrit-to-English translation |
| Mitrasamgraha | Nehrdich, Keutzer, Pawan Goyal and others; January 2026 | 391,548 Sanskrit-English sentence pairs for training translation models |
| Sanskrit Heritage platform | Gerard Huet, Inria (mirror at University of Hyderabad) | Free dictionaries, declension and conjugation, and a Sanskrit Reader that splits and tags sentences |
| Samsaadhanii | Amba Kulkarni's group, University of Hyderabad | Computational tools for Sanskrit based on Indian grammatical theory |
IndicTrans2: AI4Bharat's open-source model supports Sanskrit among all 22 scheduled languages. The paper was published in Transactions on Machine Learning Research, with an Indic-Indic model added on 1 December 2023 and long-context variants on 18 January 2025 (Source: AI4Bharat, IndicTrans2 GitHub).
ByT5-Sanskrit: a single byte-level model that reports state-of-the-art or near state-of-the-art results in word segmentation, lemmatisation, morphosyntactic tagging, Vedic dependency parsing and OCR post-correction. It appeared in Findings of EMNLP 2024 (Source: arXiv:2409.13920).
Dharmamitra: announced in August 2024, it offers segmentation, lemmatisation and tagging trained on Digital Corpus of Sanskrit annotations, alongside Sanskrit-to-English translation. It is led by Sebastian Nehrdich and Kurt Keutzer at Berkeley AI Research (Source: INDOLOGY list, 28 August 2024).
Mitrasamgraha: released in January 2026, this classical Sanskrit-English dataset is more than four times the size of the previous largest (Itihasa). Fine-tuning NLLB and Gemma on it improves translation (Source: arXiv:2601.07314).
Long-standing free tools: Huet's Sanskrit Heritage platform was released as open-source software in 2012 (Source: Sanskrit Heritage site, University of Hyderabad mirror), and Amba Kulkarni's group built Samsaadhanii at the University of Hyderabad (Source: Dharmamitra, Amba Kulkarni profile).
Manuscripts: OCR and the Gyan Bharatam Mission
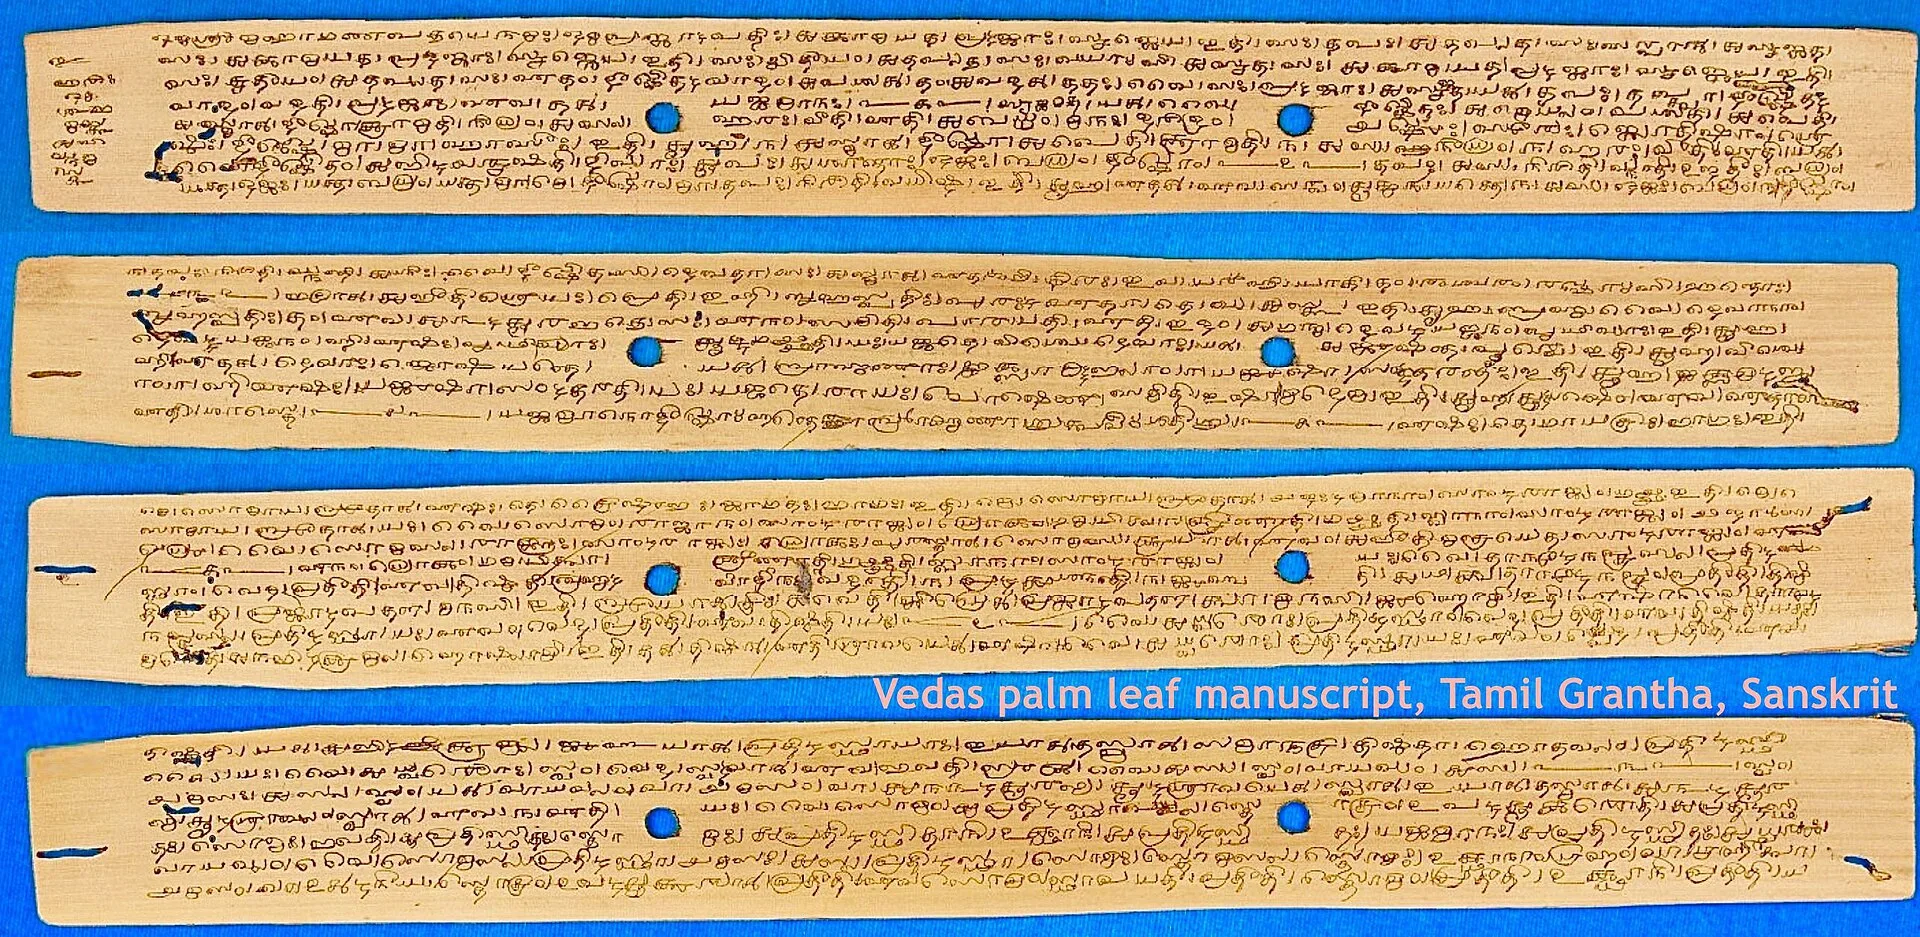
India's largest effort is about manuscripts rather than chatbots. The Gyan Bharatam Mission has an outlay of Rs 482.85 crore for 2024-31, with AI and handwritten text recognition as central tools. A PIB backgrounder of 10 September 2025 says 44.07 lakh manuscripts were already documented in the Kriti Sampada repository, and announces Gyan-Setu, a National AI Innovation Challenge covering AI cataloguing, OCR, script recognition and translation. The mission covers many languages and scripts, not only Sanskrit (Source: PIB, Gyan Bharatam Mission backgrounder).
The first Gyan Bharatam International Conference was held at Vigyan Bhawan, New Delhi, on 11-13 September 2025, where PM Modi launched the Gyan Bharatam Portal. It closed with the New Delhi Declaration on preserving, digitising and sharing manuscript knowledge, and its sessions covered AI-driven handwritten text recognition and script decipherment (Source: The Tribune, 14 September 2025).
2026: universities, LLMs and the research community
- Sanskrit Heritage Model (September 2026): Finance Minister Nirmala Sitharaman launched this Sanskrit LLM, built by Articul8 AI, at the Madras Sanskrit College in Chennai, and called for AI tools to explain grammar, sandhi and samasa and to index manuscripts held worldwide. Its capabilities had not been independently evaluated in the sources we found (Source: DT Next, 16 September 2026). Note: this is a different project from Huet's older Sanskrit Heritage platform.
- A 'native' Sanskrit LLM (announced plan): in January 2026 a project involving MDS Sanskrit College, IIT Madras and the Kuppuswami Sastri Research Institute was reported, drawing on Paninian grammar and aiming to process over 110,000 manuscripts. No official IIT Madras announcement, benchmark or release was found (Source: Organiser, 30 January 2026).
- B.Tech in AI at a Sanskrit university: Central Sanskrit University received AICTE approval for a B.Tech in AI and Data Science at its Nashik campus from 2026-27, with an intake of 60 through JEE, combining AI, NLP and computational linguistics with Sanskrit grammar and philosophy (Source: The Tribune, 29 May 2026).
- ISCLS symposia: the 7th International Sanskrit Computational Linguistics Symposium met in Auroville on 15-17 February 2024 (10 full papers, 18 demonstrations), and the 8th at IIT Roorkee on 9-11 March 2026, covering machine translation, speech and even Sanskrit poetry generation (Source: ACL Anthology, 7th ISCLS; Source: ACL Anthology, 8th ISCLS).
Why Sanskrit is hard for AI: a worked example
Take one everyday sandhi rule. When a word ending in a or aa meets a word beginning with i or ii, the two vowels merge into e. Panini states this in the short rule traditionally numbered 6.1.87, aad gunah. So deva (god) + indra gives devendra.
Going forward is easy: apply the rule. Going backward, which is what a computer reading a text must do, is hard. Faced with devendra, a machine has to guess where the word boundary is and which of four possible vowel pairs (a+i, a+ii, aa+i, aa+ii) produced the e. Multiply that by every sandhi junction in a long compound, and add the fact that the same form can be several grammatical cases, and you see why segmentation is a research problem in its own right. That is exactly the task ByT5-Sanskrit and Dharmamitra are built to tackle.
Data is the second problem. The IndicParam benchmark (November 2025) places Sanskrit among the "extremely low-resource" languages; across 20 models on 11 languages, the best average accuracy was only 58% (Gemini-2.5). DharmaBench (IJCNLP-AACL 2025) likewise calls Sanskrit a low-resource historical language (Source: Maheshwari et al., IndicParam, arXiv:2512.00333).
Myth vs fact
| Myth | What the evidence says |
|---|---|
| NASA declared Sanskrit the best language for computers. | The claim traces to Rick Briggs's 1985 AI Magazine paper, which compared Sanskrit grammarians' methods to AI knowledge representation. It made no such claim, and no NASA programme exists. |
| Sanskrit is the 'most suitable language for computer software'. | Briggs never said this; Dilip D'Souza calls the phrase essentially meaningless. Computers need unambiguous instructions that no natural language provides. The often-cited 1987 Forbes report cannot be found. |
| Sanskrit's precise grammar makes it easy for AI. | Rich morphology, sandhi and compounding make it hard, and too little digital training data exists. |
| AI translation of Sanskrit is now solved. | The 2026 Mitrasamgraha study still reports serious difficulty with complex compounds, philosophical concepts and multi-layered metaphors. |
Sources: Source: Rick Briggs, AI Magazine (1985); Source: Scroll.in (Dilip D'Souza); Source: ByT5-Sanskrit; Source: Mitrasamgraha. Read the full story in our guide to the NASA-Sanskrit computer myth.
How learners and NRI families can use AI for Sanskrit
- Use AI to split and parse: when a shloka line will not make sense, a segmenter such as the Sanskrit Heritage Reader or Dharmamitra can suggest where the words divide. Treat the result as a suggestion.
- Treat translations as drafts: compare machine output with a published translation, especially for shastra and scripture, where scholarly review remains necessary.
- Ask about grammar, then verify: general chatbots can explain sandhi or samasa, but benchmarks show they make mistakes in Sanskrit. Check with a dictionary or a teacher.
- Keep the teacher: pronunciation, chanting and meaning in context still come best from a guru or class. For apps and online courses for children abroad, see our Sanskrit 2026 AI tools, apps and courses guide.
Frequently asked questions
Is there a Sanskrit AI model I can use today?
Several open research tools exist. AI4Bharat's IndicTrans2 supports Sanskrit among all 22 scheduled Indian languages, ByT5-Sanskrit handles tasks such as word segmentation and lemmatisation, and Dharmamitra from UC Berkeley offers grammatical analysis and Sanskrit-to-English translation. Gerard Huet's Sanskrit Heritage platform provides free dictionaries and a Sanskrit Reader.
Is Sanskrit easy for AI because its grammar is so precise?
No. Researchers describe Sanskrit as morphologically rich and notoriously challenging for NLP. Sandhi and compounding make segmentation and translation hard, and 2025 benchmarks classify Sanskrit as low-resource or extremely low-resource because little digital training data exists.
Did NASA say Sanskrit is the best language for computers?
No. The claim traces to Rick Briggs's 1985 AI Magazine paper, which compared the methods of Sanskrit grammarians with AI knowledge representation. It did not say Sanskrit is the best language for software, and no NASA programme to that effect exists.
Can I trust AI translations of the Gita or Upanishads?
Use them as a first draft, not a final authority. Even the largest Sanskrit-English dataset, released in January 2026, reports serious difficulty with complex compounds, philosophical concepts and layered metaphors. Check important passages against a scholarly translation or a teacher.
What is the Gyan Bharatam Mission?
A national manuscript mission with an outlay of Rs 482.85 crore for 2024-31, using AI and handwritten text recognition as central tools. By September 2025, 44.07 lakh manuscripts had been documented in the Kriti Sampada repository. It covers manuscripts in many languages and scripts, not only Sanskrit.
Who launched a Sanskrit LLM in 2026?
In September 2026 Finance Minister Nirmala Sitharaman launched the Sanskrit Heritage Model, built by Articul8 AI, at the Madras Sanskrit College in Chennai. Its capabilities had not been independently evaluated in the sources we found. A separate native Sanskrit LLM project involving IIT Madras was reported in January 2026 as a plan.
Related guides
- Sanskrit 2026: AI tools, apps and online courses for NRI families
- Panini's Sanskrit grammar and computer science
- The NASA-Sanskrit computer myth and Rick Briggs (1985)
- AI Gita chatbots: accuracy and ethics
- Madhava and the Kerala school: infinite series for pi
- Quantum computing explained for Hindus
Editor's note (9 October 2026)
Every model, date, number and quotation on this page comes from the sources linked in the text: research papers on arXiv and in the ACL Anthology, AI4Bharat's repository, the Press Information Bureau, and reporting by The Tribune, DT Next and Organiser. Items reported only as plans, such as the IIT Madras-linked Sanskrit LLM, are labelled as such, and launched models that have not been independently evaluated are flagged. The sandhi example illustrates a standard rule of Panini's grammar. This page will be updated as new Sanskrit AI tools are released and evaluated.
You might also like
Sanskrit 2026 — Best AI Tools, Apps & Online Courses for NRI Families Teaching Samskritam Abroad
Did NASA Say Sanskrit Is the Best Language for Computers? What Rick Briggs' 1985 Paper Actually Said
Panini and Computer Science: How the Ashtadhyayi Works Like a Formal Rule System, and the 'Panini-Backus Form' Story